At $23,750 per minute, the cost of unplanned downtime for a modern enterprise isn’t just a technical failure; it’s a direct threat to organizational stability and market reputation. As global traffic volumes reach unprecedented levels in 2026, the reliance on professional performance testing services has transitioned from a quality assurance luxury to a fundamental requirement for digital survival. You likely recognize that a single second of latency can erode customer trust faster than any marketing campaign can build it. We understand the pressure of managing complex cloud environments where finding specialized talent feels as difficult as preventing the bottlenecks themselves.

This guide provides a strategic roadmap to help you evaluate and implement performance testing services that transform your infrastructure into a resilient, high-performing asset. You’ll discover how to integrate automated frameworks into your DevOps pipeline while adhering to the updated ISO/IEC 25010:2023 standards for software quality. We’ll examine the methodologies required to achieve zero-downtime releases and reduce infrastructure costs through precise optimization. By the end of this article, you’ll have a clear framework for selecting a partner capable of securing your long-term operational stability and scalable growth.

Key Takeaways

  • Align your digital assurance strategy with high-stakes business objectives by identifying the critical distinctions between load, stress, and endurance testing.
  • Utilize a sophisticated evaluation framework to audit performance testing services based on technical depth, tool proficiency, and global compliance standards.
  • Master the five-step methodology for automating performance validation within your DevOps workflow, leveraging the Atlassian ecosystem to synchronize development and quality assurance.
  • Secure long-term operational stability and reduced infrastructure costs by adopting a proactive model that focuses on engineering performance, ensuring reliability, and empowering growth.

Defining the Role of Performance Testing Services in Modern Enterprise Ecosystems

Performance testing is the systematic evaluation of a system’s speed, responsiveness, and stability under a defined workload. While traditional approaches often treated this as a final hurdle before launch, modern performance testing services serve as the strategic backbone of digital assurance. They provide a structured framework for identifying bottlenecks before they impact the end user. This shift from reactive troubleshooting to proactive performance engineering is essential for global organizations operating in hyper-competitive markets. When infrastructure remains resilient, executive leadership gains the peace of mind necessary to focus on innovation rather than crisis management. By prioritizing stability, precision, and progress, companies can ensure their digital assets remain competitive in a landscape where failure isn’t an option.

The complexity of 2026 cloud-native environments requires a more sophisticated approach than simple load generation. Effective software performance testing involves a deep analysis of how microservices, APIs, and third-party integrations interact under pressure. It’s no longer enough to know that a system works; you must know exactly when and why it might break. This level of insight allows technical managers to make data-driven decisions about infrastructure scaling and resource allocation, ultimately protecting the organization’s bottom line.

The Business Impact of Optimized Performance

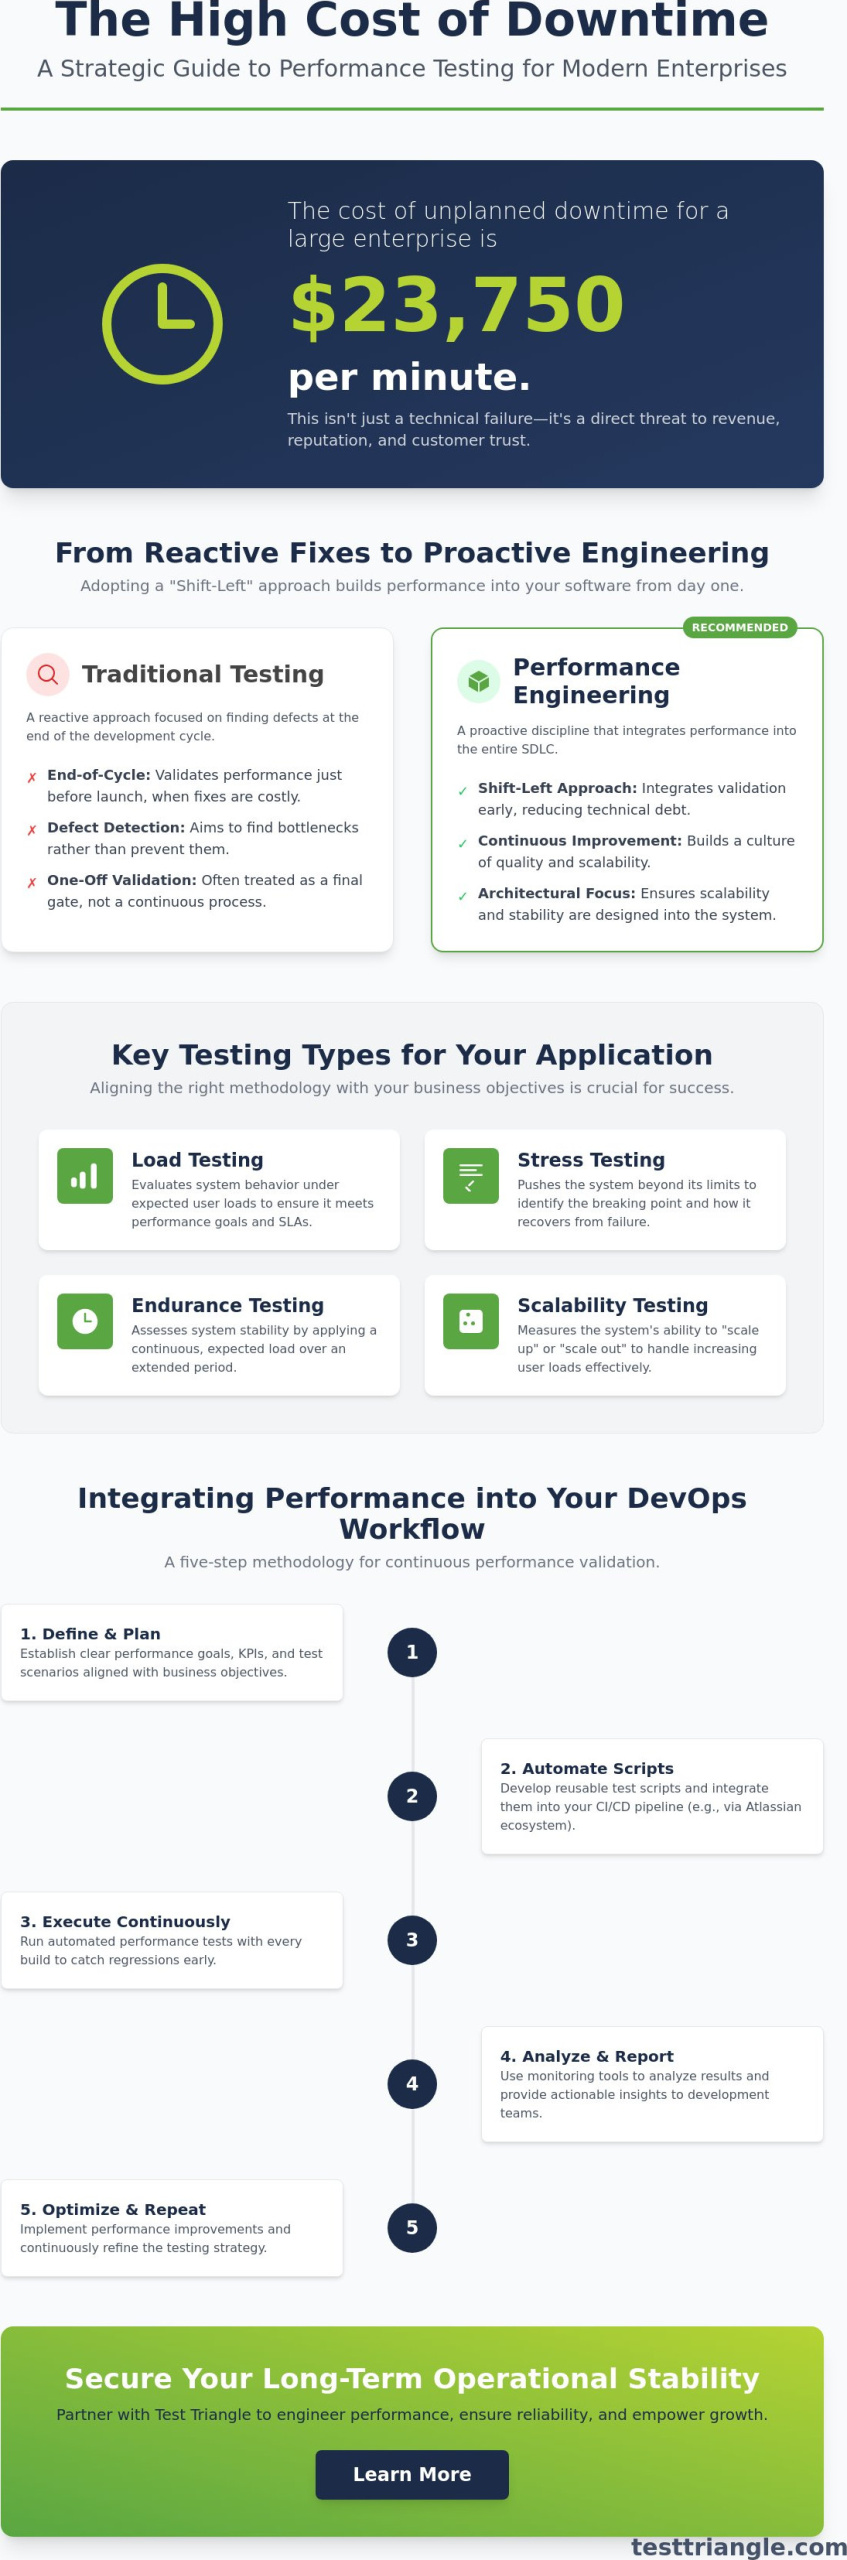
In the current digital economy, milliseconds define the boundary between a completed transaction and a lost customer. Research indicates that the average cost of unplanned downtime is $14,056 per minute, a figure that can escalate to $23,750 for large-scale enterprises. For sectors like finance and healthcare, the cost of failure extends beyond immediate revenue loss to include severe brand erosion and legal liability. High-load applications require consistent optimization to maintain user engagement and long-term loyalty. When you invest in professional performance testing services, you’re not just buying a report; you’re securing your brand’s reputation and ensuring revenue retention through a seamless user experience.

Performance Testing vs. Performance Engineering

It’s vital to distinguish between traditional, one-off testing and the more comprehensive discipline of performance engineering. While testing validates performance against specific benchmarks at the end of a cycle, engineering builds quality directly into the architecture from day one. This “Shift-Left” approach integrates performance validation earlier in the Software Development Life Cycle (SDLC), ensuring that scalability isn’t an afterthought. By adopting these advanced performance testing services, companies can transition from simple defect detection to a culture of continuous improvement. This methodology ensures that every code release contributes to a more stable, scalable, and secure environment, reducing the overall cost of technical debt.

How to Identify Key Performance Testing Types for Your Application

Selecting the appropriate testing methodology requires a deep alignment between technical execution and specific business milestones. In 2026, the complexity of distributed systems demands a more nuanced approach than a one-size-fits-all test script. Modern performance testing services now leverage AI-augmented simulations to model realistic user behavior, ensuring that your digital infrastructure is prepared for actual human interaction rather than just synthetic traffic. Whether you’re preparing for a global product launch or managing a complex cloud migration, identifying the right testing type is critical for maintaining operational continuity.

Scalability testing plays a pivotal role during cloud migration projects, as it validates the system’s ability to scale up or out in response to fluctuating demand. By utilizing enterprise performance testing strategies, organizations can avoid the common pitfall of over-provisioning infrastructure, which often leads to unnecessary cloud expenditures. A disciplined approach ensures that every resource allocated contributes directly to system responsiveness and user satisfaction.

Load Testing for Daily Operational Stability

Load testing is the baseline for all performance benchmarks. It allows you to determine your “normal” load by simulating expected concurrent user growth while monitoring vital metrics such as throughput, latency, and error rates during peak hours. By establishing these baselines, technical managers can identify the exact point where response times begin to degrade. This data is indispensable for long-term capacity planning and ensuring that daily operations remain fluid and predictable.

Stress and Spike Testing: Preparing for the Unexpected

While load testing focuses on the expected, stress and spike testing prepare your systems for the volatile reality of modern markets. Stress testing involves pushing a system to its breaking point to evaluate how it recovers and whether it maintains “graceful degradation” under extreme pressure. Spike testing, conversely, simulates sudden traffic surges common in the retail and media industries, such as a Black Friday sale or a viral news event. These tests ensure that your application doesn’t just survive the surge but remains responsive enough to protect revenue. If you’re unsure which scenario poses the highest risk to your operations, you can consult with our performance engineering experts to design a custom simulation profile.

Endurance and Volume Testing for Long-Term Reliability

Long-term reliability is often compromised by issues that don’t appear in short-term tests, such as memory leaks or resource exhaustion. Endurance testing involves running a consistent load over extended periods to identify these hidden vulnerabilities. Similarly, volume testing manages large data sets to ensure database performance remains consistent as your records grow. Integrating these practices into your broader software and digital assurance testing strategy is essential for maintaining a stable enterprise ecosystem. This comprehensive approach ensures that your infrastructure remains resilient, scalable, and high-performing throughout its entire lifecycle.
Performance Testing Services: The 2026 Strategic Guide to Enterprise Scalability

Comparing Performance Testing Service Providers: A Strategic Evaluation Framework

Selecting a partner for performance testing services requires a rigorous audit that extends beyond surface-level metrics or generic case studies. As enterprise architectures become increasingly fragmented across multi-cloud environments, the ability to evaluate a provider’s technical depth, operational maturity, and strategic alignment becomes a prerequisite for project success. A robust evaluation framework must prioritize a partner’s capacity to act as a steady hand, guiding your organization through the complexities of large-scale technological evolution while ensuring long-term operational stability. By focusing on a combination of technical rigor and business-centric outcomes, leadership can transition from a state of uncertainty to one of precision, partnership, and progress.

The distinction between a mere service provider and a strategic collaborator often lies in their approach to tool utilization. We believe that vendor-agnostic expertise is significantly superior to proprietary tool locks, as it allows for the selection of the most effective technology for your specific stack. This flexibility ensures that your testing framework remains adaptable as your digital infrastructure evolves. Furthermore, global enterprises should examine the provider’s delivery models, assessing how their managed outsourcing services or specialized staffing solutions integrate into existing internal workflows to provide seamless, scalable support.

Technical Proficiency and Tool Stack Audit

A comprehensive technical audit should verify the provider’s mastery of industry-standard tools such as Apache JMeter 5.6.3, LoadRunner, and Gatling. In 2026, proficiency must extend into cloud-native testing environments, specifically within AWS, Azure, and Google Cloud platforms. You should evaluate their ability to develop custom scripts for complex API and microservices architectures, ensuring that the testing environment mirrors the intricacies of your production ecosystem. This technical depth is essential for identifying subtle performance regressions that standard, out-of-the-box configurations might overlook.

Strategic Alignment and Industry Expertise

Specialized knowledge in highly regulated sectors, such as Finance and Pharma, is non-negotiable due to the stringent compliance and security standards these industries demand. When auditing potential partners, look for those who demonstrate a deep understanding of the strategic value of QA outsourcing and its role in driving organizational growth. A comprehensive digital assurance strategy should also account for platform-specific failures, which is why pairing performance validation with robust compatibility testing services ensures your application delivers a consistent experience across every device, browser, and operating system your users depend on. The most effective performance testing services don’t just deliver raw data; they provide actionable insights that connect technical performance to executive-level business objectives. This ensures that every test conducted contributes directly to risk reduction and the empowerment of your digital transformation journey.

How to Integrate Performance Testing into a Continuous DevOps Workflow

Performance validation is no longer a siloed event that occurs at the end of a development cycle. In 2026, 68% of enterprises have already embedded performance testing services directly into their CI/CD pipelines to ensure continuous reliability with every code commit. This integration transforms performance from a reactive concern into a proactive architectural discipline. By automating these checks, organizations can identify regressions in real time, preventing costly bottlenecks from reaching production. Efficiency is the result of discipline. A scalable testing framework allows your team to maintain high velocity without sacrificing the stability that global users expect.

Adopting a “performance as code” philosophy ensures that scalability requirements are treated with the same priority as functional features. This approach requires a methodical feedback loop that connects development, operations, and quality assurance teams. When performance metrics are transparent and integrated into daily workflows, the entire organization becomes invested in the system’s long-term health. Setting strict “Performance Budgets” for development teams provides a clear ceiling for latency and resource consumption, ensuring that new features don’t inadvertently degrade the user experience. Complementing this discipline with robust software test automation services ensures that regression suites scale alongside your deployment frequency without creating unsustainable manual overhead.

Step-by-Step: Automating the Performance Feedback Loop

Automating the feedback loop requires a structured 5-step process to ensure consistent results and actionable data. This methodology allows teams to catch issues early when they’re still inexpensive to fix.

  • Step 1: Define performance requirements as code within your Bitbucket or GitHub repository to ensure version-controlled benchmarks.
  • Step 2: Trigger automated load tests on every major build or pull request to validate performance against your established budgets.
  • Step 3: Analyze results against historical benchmarks using AI-driven analytics to distinguish between minor fluctuations and genuine regressions.
  • Step 4: Fail the build automatically if performance thresholds are not met, preventing substandard code from progressing through the pipeline.
  • Step 5: Document and remediate identified defects within your project management ecosystem to maintain a clean performance profile.

Leveraging Atlassian and ServiceNow for Performance Governance

Effective governance relies on the seamless integration of testing results into the tools your teams use every day. By synchronizing test data with Jira, you provide developers with immediate visibility into performance defects, allowing for rapid remediation within their standard sprint cycles. Utilizing a strategic ServiceNow implementation allows you to track performance trends in production environments and manage incidents with greater precision. This holistic view ensures that your Atlassian implementation strategy is informed by real-world performance data. If you’re ready to modernize your pipeline, speak with our DevOps consultants today to build a framework that supports sustainable growth.

Test Triangle: Engineering Performance, Ensuring Reliability, Empowering Growth

As global enterprises navigate the complexities of 2026, the need for a disciplined approach to performance testing services has never been more acute. Test Triangle stands as a strategic visionary in this landscape, offering a unique blend of technical rigor and human expertise to manage your digital infrastructure. We don’t just identify defects; we provide the roadmap for systemic improvement and scalable growth. Our personality is built on precision, partnership, and progress, ensuring that your organization remains resilient against the volatility of modern traffic demands. By positioning ourselves as a reliable long-term collaborator, we help you transition from the anxiety of potential system failure to the confidence of operational stability.

Our Methodology: The Three Pillars of Performance

Our strategic approach is built upon three distinct phases designed to lead your organization from a general need for improvement to a specific technical solution. Each phase is executed with a focus on risk reduction and large-scale technological evolution.

  • Analyze: We begin with a deep-dive into your architecture to identify hidden risks and potential bottlenecks that could compromise your user experience. This phase ensures that we understand the methodology behind your current system before proposing specific actions.
  • Optimize: Through the implementation of precision testing, we refine code and infrastructure efficiency to ensure peak performance under any workload. We utilize the latest tools, such as Apache JMeter 5.6.3, to anchor our execution in recognized global benchmarks.
  • Empower: We provide the training and tools necessary for long-term operational stability. This empowers your team to maintain a scalable testing framework that fits seamlessly into your existing DevOps pipeline.

Partnering for Scalable Success

Building a resilient digital ecosystem requires a collaborator who understands the nuances of global industry platforms. Our managed outsourcing services provide a foundation for long-term QA stability, allowing your internal teams to focus on core innovation while we maintain the integrity of your releases. Our adaptable approach to service delivery means we can seamlessly integrate into your existing culture, whether you require specialized staffing solutions to fill technical gaps or a fully managed end-to-end testing program. This flexibility ensures that technical rigor is never sacrificed for speed.

By leveraging our deep expertise in AWS and our comprehensive Atlassian implementation strategies, we ensure that your testing standards meet world-class benchmarks for security and speed. We invite you to a strategic technology roadmapping session to address your specific bottlenecks and design a scalable framework that supports your digital transformation. Consult with our performance testing experts today to secure your organizational progress through a combination of expert human insight and industry-leading technical tools.

Securing Digital Resiliency: Precision, Partnership, Progress

Achieving enterprise scalability in 2026 requires a transition from reactive troubleshooting to a culture of proactive performance engineering. By embedding automated validation into your CI/CD pipeline and utilizing a criteria-based framework for partner selection, your organization can effectively mitigate the significant financial risks associated with unplanned downtime. High-performing infrastructure is no longer merely a technical objective; it’s a strategic imperative that ensures your brand remains competitive in an increasingly volatile global market. Stability is the result of disciplined execution and visionary planning.

Test Triangle provides a sophisticated approach to performance testing services, leveraging over a decade of expertise in global IT services to maintain your operational stability. Our strategic partnerships with Atlassian, ServiceNow, and AWS, alongside specialized staffing models for the pharmaceutical and finance sectors, offer the technical rigor necessary for complex, regulated environments. We invite you to partner with Test Triangle for authoritative performance testing services to transform your technical challenges into sustainable growth. Your journey toward a resilient, high-performing digital future begins with a single strategic step.

Frequently Asked Questions

What are the most critical metrics to track during performance testing?

The primary metrics for evaluating system health include response time, throughput, and error rates. Technical managers must also monitor resource utilization such as CPU and memory consumption to identify underlying hardware bottlenecks. These data points provide the quantitative evidence needed to validate that your application meets the updated ISO/IEC 25010:2023 standards for interaction capability and flexibility.

How much do performance testing services typically cost for an enterprise application?

Investment levels for professional performance testing services depend on the complexity of your digital ecosystem and the scale of the required simulations. Factors influencing the total expenditure include tool licensing fees, the depth of specialized staffing required, and the duration of the engagement. Organizations should focus on the return on investment derived from risk reduction and the prevention of downtime costs, which average $23,750 per minute for global enterprises.

Can performance testing be fully automated within a CI/CD pipeline?

Yes, modern performance testing services prioritize the integration of automated checks directly into your DevOps workflow. By utilizing a “tests as code” approach, teams can trigger load simulations with every build to ensure that new features don’t introduce performance regressions. This methodology allows for a faster feedback loop and supports the shift-left strategy discussed earlier in this guide.

What is the difference between load testing and stress testing?

Load testing evaluates how a system performs under expected traffic volumes to ensure daily operational stability. Stress testing, by contrast, pushes the application beyond its specified limits to identify the exact breaking point and evaluate its recovery capabilities. While load testing focuses on meeting service level agreements, stress testing ensures the system can maintain graceful degradation during extreme surges.

How long does a typical performance testing engagement take?

The duration of an engagement varies based on whether the project is a one-off audit or a transition to continuous performance engineering. Initial baseline establishment and environment configuration typically require several weeks of intensive analysis. Once the framework is established, subsequent regression tests can be executed rapidly as part of your standard release cycle.

Is performance testing necessary for cloud-native applications?

Performance validation is critical for cloud-native architectures due to the inherent complexity of microservices and distributed APIs. While cloud providers offer auto-scaling, you must test these triggers to ensure they respond quickly enough to prevent latency. Testing also prevents over-provisioning, which helps in reducing unnecessary infrastructure costs through precise optimization.

How do I choose between open-source and commercial performance testing tools?

The decision rests on your team’s technical proficiency and your specific integration requirements. Open-source tools like Apache JMeter 5.6.3 offer significant flexibility for teams comfortable with custom scripting. Commercial platforms often provide more robust reporting and dedicated support, which can be beneficial for highly regulated industries requiring extensive documentation.

What happens if my application fails a performance test?

A failed test serves as a strategic diagnostic tool rather than a project setback. The results are used to pinpoint the specific component or code block causing the bottleneck, allowing for targeted remediation. Once the issues are addressed, the system is re-tested to confirm that the optimizations have successfully restored performance to its required benchmarks.

Paul Guy

Article by

Paul Guy

Paul serves as the Marketing Director at Test Triangle, where he leads a global team in driving growth through strategic B2B marketing and brand communications. With a strong emphasis on measurable outcomes and sustainable performance, he plays a pivotal role in aligning marketing functions to enhance customer engagement and accelerate business impact. Under his leadership, marketing initiatives have consistently delivered significant returns on investment, elevated brand visibility, and strengthened the company's presence across key markets.
What if the very platform designed to accelerate your team’s digital transformation has become the primary anchor slowing down your operational velocity? Most enterprise leaders recognize that Jira is indispensable for scale, yet they find themselves buried under a mounting pile of manual provisioning requests and a configuration sprawl that threatens system stability. To effectively reduce jira administration overhead, organizations must shift their perspective from reactive maintenance to a sophisticated, standardized governance framework that prioritizes long-term platform health over short-term fixes.

You likely understand the frustration of managing an environment where custom fields have spiraled toward the 700-field limit or where manual user de-provisioning consumes hours of your team’s week. We promise that by implementing the strategies outlined in this guide, you’ll reclaim administrative time for high-level strategic initiatives and build a self-sustaining ecosystem. We’ll examine the methodology behind field optimization, the automation of routine workflows, and the critical steps needed to align your environment with Atlassian’s evolving cloud-first roadmap and the 2029 Data Center end-of-life milestones.

Key Takeaways

  • Identify architectural inefficiencies within your platform by moving beyond reactive ticket management toward a standardized global scheme that addresses the majority of team requirements.
  • Discover how to reduce jira administration overhead by leveraging native automation tools and Identity Provider integrations to eliminate manual user provisioning.
  • Empower internal teams through a disciplined delegated administration model that allows project leads to manage local versions and components without compromising system integrity.
  • Evaluate the strategic advantages of offloading operational complexity to specialized Atlassian Consulting partners to ensure long-term stability and platform performance.
  • Optimize system responsiveness and security by auditing redundant permission schemes and consolidating configuration sprawl into a scalable governance framework.

Diagnosing the Root Causes of Jira Administration Overhead

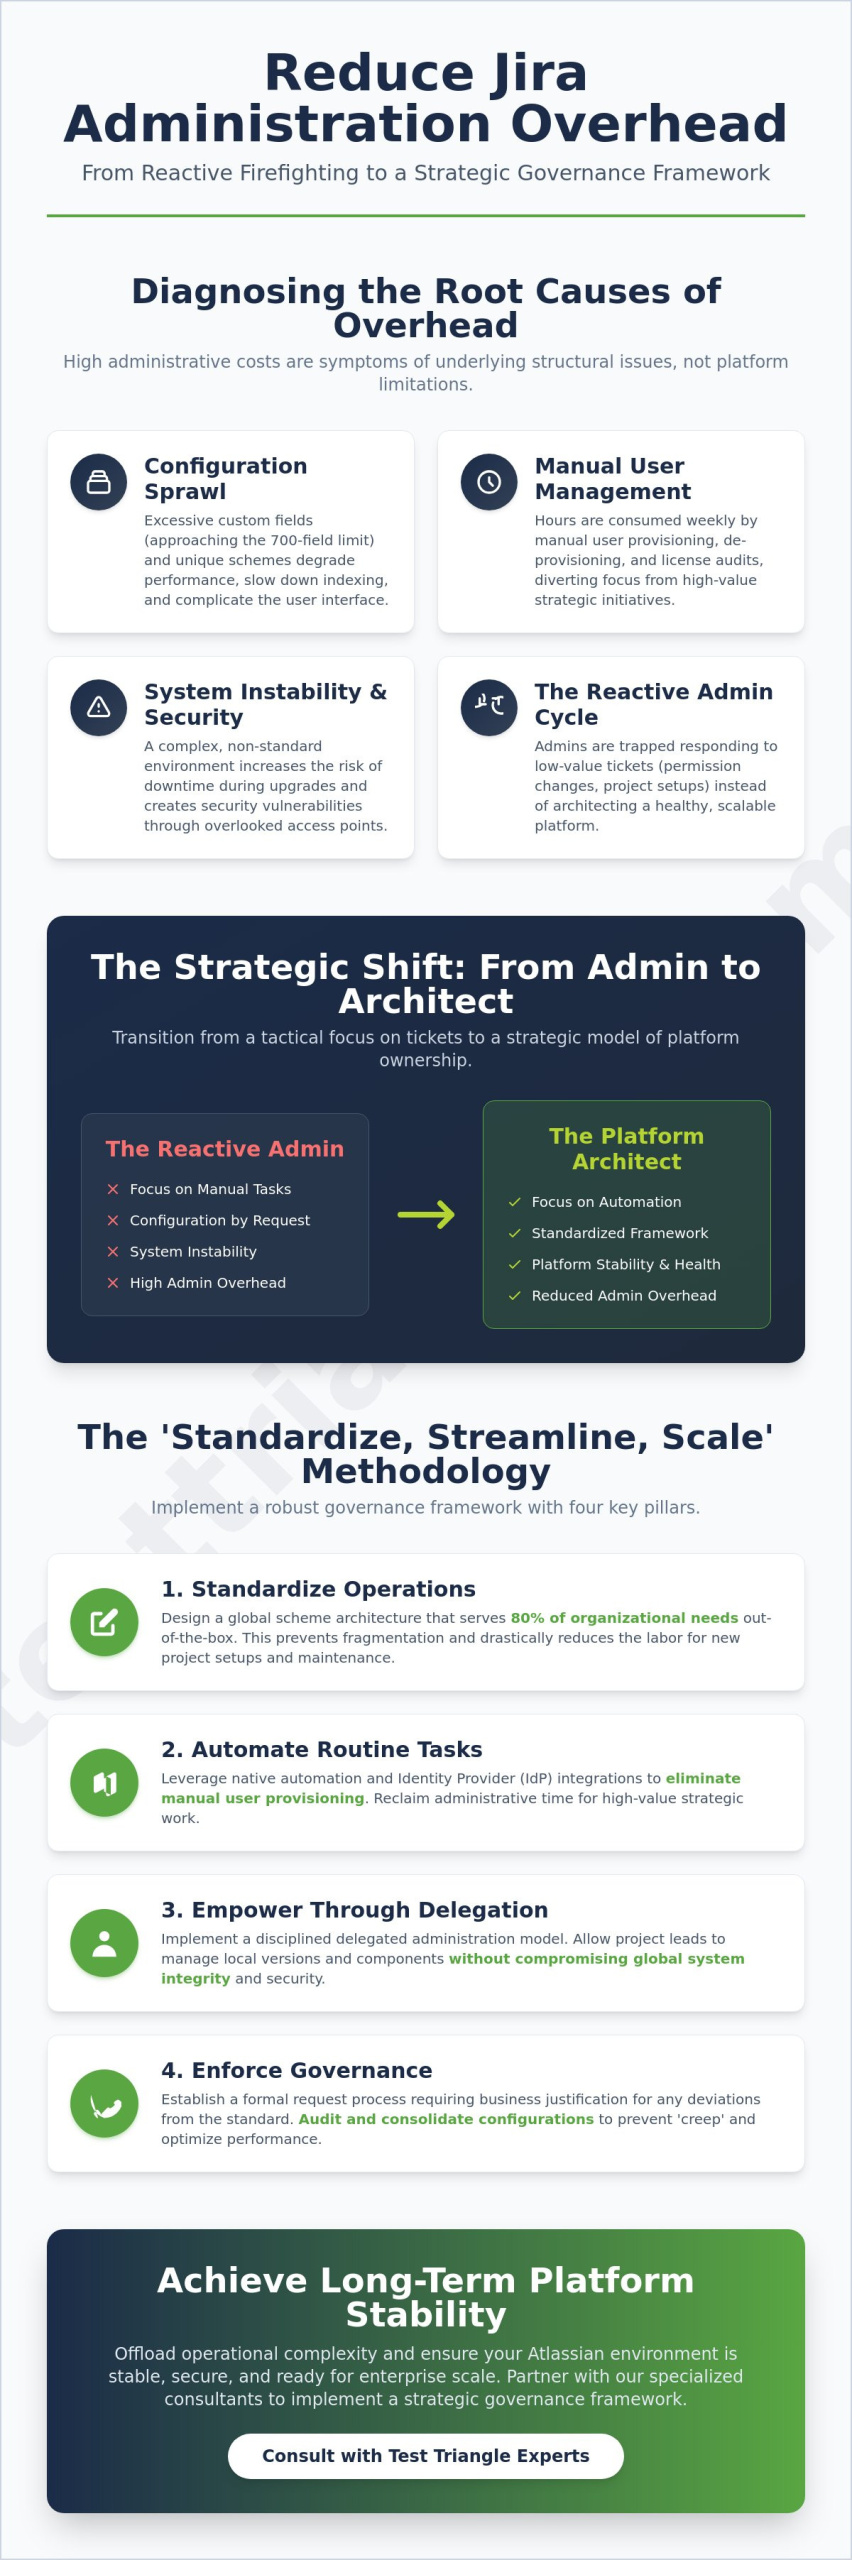
Organizations often view administrative burden as an inevitable byproduct of growth, yet this perspective ignores the underlying structural failures that compound over time. High administrative costs are rarely the result of platform limitations; rather, they’re symptoms of a fragmented Project governance framework that prioritizes individual team requests over global system health. To effectively reduce jira administration overhead, leadership must first acknowledge that most administrative labor is actually “rework” caused by a lack of standardization. When every project team is granted a unique set of custom fields and permission schemes, the resulting configuration sprawl creates a labyrinth that even seasoned admins struggle to navigate. This complexity doesn’t just frustrate users; it degrades system performance and increases the likelihood of security vulnerabilities through overlooked access points.

Beyond the technical debt of custom configurations, manual user management and license reconciliation represent a significant drain on internal resources. Research indicates that organizations automating user management can significantly lower licensing costs by identifying and deactivating inactive accounts. Without a strategic approach, IT teams remain trapped in a cycle of manual de-provisioning and license audits, diverting their expertise away from high-value Atlassian Consulting initiatives that could drive actual business transformation.

The Hidden Cost of Configuration Sprawl

The proliferation of custom fields acts as a silent tax on platform health. Atlassian recently noted that Jira Cloud can support up to 700 fields per space, but reaching these limits often leads to severe performance degradation. Excessive fields slow down issue indexing and complicate the user interface, making it harder for teams to find relevant information. A disciplined audit of field usage is essential to identify redundant or unused candidates for consolidation. Reducing this sprawl doesn’t just clean up the UI; it minimizes the risk of system downtime during upgrades or migrations, especially as organizations prepare for the 2029 Data Center end-of-life milestone.

Manual vs. Strategic Administration

Many IT departments operate in a “Reactive Admin” cycle, where the majority of their week is consumed by low-value support tickets for simple permission changes or project setups. This tactical focus creates a ceiling on team morale and prevents the transition toward a “Platform Architect” model. By quantifying the time lost to these routine tasks, leadership can justify the shift toward a self-service environment. True strategic administration involves designing a global scheme architecture that serves 80% of organizational needs without requiring manual intervention for every new request. This evolution empowers teams while ensuring the platform remains stable, secure, and ready for enterprise-scale growth.

Implementing a Robust Governance Framework to Standardize Operations

Transitioning from a reactive support model to a proactive governance framework requires more than just technical adjustments; it demands a cultural shift toward institutional discipline. To effectively reduce jira administration overhead, organizations must implement a ‘Standardize, Streamline, Scale’ methodology that treats project configuration as a shared corporate asset rather than a localized convenience. By designing a global scheme architecture that addresses 80% of team requirements through universal configurations, administrators can prevent the fragmentation that typically leads to performance bottlenecks. This strategic alignment ensures that every new project inherits a proven, secure foundation, significantly reducing the labor involved in manual setup and long-term maintenance.

A critical component of this evolution involves Implementing IT Governance to validate any requests for deviation from the standard. Establishing a formal request process that requires rigorous business justification for new custom fields or unique workflows prevents the ‘configuration creep’ identified in previous sections. For enterprises looking to accelerate this transition, our IT Service Management Services provide the structural expertise needed to align platform capabilities with business objectives. Documentation of these policies serves as the final pillar, ensuring that as the organization grows, the logic behind configuration decisions remains transparent and consistent.

Creating Shared Schemes for Scalability

Scalable governance relies on the deployment of universal permission and notification schemes that serve multiple projects simultaneously. By prioritizing Project Roles over individual user assignments, administrators can significantly reduce jira administration overhead by delegating day-to-day access management to project leads without granting global administrative rights. This approach simplifies the burden of security audits and ensures that standardized access patterns are applied consistently across the entire instance, protecting data integrity while fostering team autonomy.

The Role of a Jira Steering Committee

Maintaining a balance between team-level flexibility and enterprise-level stability requires the oversight of a Jira Steering Committee. This body, comprised of technical leads, business stakeholders, and compliance officers, approves major architectural changes and sets clear KPIs for administrative efficiency. By monitoring metrics such as field-to-project ratios and ticket resolution times, the committee ensures the platform remains agile. If your team is struggling to define these benchmarks, you might consider how a specialized assessment can help clarify your governance roadmap.

How to Reduce Jira Administration Overhead: A Strategic Guide to Scalable Governance

Automating Routine Tasks to Reclaim Administrative Time

While a robust governance framework establishes the necessary boundaries, automation serves as the engine that drives operational velocity. Relying on manual intervention for every status transition or field update is a recipe for administrative burnout and systemic delays. By leveraging native ‘Automation for Jira’ capabilities, organizations can reduce jira administration overhead through the creation of sophisticated rules that handle repetitive tasks without human oversight. This strategic shift allows your internal experts to focus on complex architectural challenges rather than the minutiae of daily maintenance, effectively transforming the IT department from a bottleneck into a facilitator of growth.

Beyond simple workflow triggers, the ability to execute bulk updates across hundreds of projects is essential for maintaining a standardized environment. Utilizing specialized scripts or third-party applications to synchronize permission schemes or update custom field configurations across the entire instance prevents the manual drift that often occurs in large-scale deployments. This automated synchronization ensures that your governance policies are enforced universally, protecting the system from the performance degradation typically associated with unmanaged configuration sprawl. By implementing these systemic controls, you establish a self-regulating ecosystem that maintains its own integrity.

Strategic User Provisioning and License Cleanup

Connecting your Jira environment to a central HRIS or Active Directory is a foundational step in scaling your infrastructure. This integration allows for the automated deactivation of users who haven’t logged in for 90 days, a practice that directly preserves your budget. Given that Jira Data Center costs have increased by approximately 111% between 2019 and 2026, maintaining strict license hygiene is no longer optional; it’s a financial imperative. For organizations navigating the complexities of these integrations, our Atlassian Implementation services provide the technical rigor required to ensure a seamless and secure transition.

Workflow Automation for Administrative Requests

Administrative requests themselves can be managed with the same precision as development tasks by building a dedicated ‘Jira for Jira’ project. This internal service desk uses template-based project creation to ensure every new workspace automatically adheres to your established governance rules from day one. This level of standardization significantly reduces the volume of ‘where is my ticket’ queries through automated status reporting and notifications. By providing teams with a clear, automated path for their requests, you eliminate the friction of manual follow-ups and ensure that all platform changes are documented and approved according to your global standards.

Empowering Teams Through Delegated Administration

Centralizing every minor configuration change within a single IT department creates an artificial ceiling on organizational agility and systemic velocity. While the governance framework established in previous sections provides the necessary structure, true scalability is achieved only when power is distributed effectively. To reduce jira administration overhead, enterprise leaders must transition toward a model of delegated administration, where project-level decisions are handled by the teams closest to the work. This shift doesn’t imply a loss of control; rather, it represents a sophisticated evolution of the administrative role from a tactical gatekeeper to a strategic enabler who provides the tools for self-sufficiency.

Implementing this decentralized approach requires a disciplined framework to ensure that localized flexibility doesn’t compromise global stability. By utilizing ‘Extended Project Administration’ features in a controlled manner, organizations can allow project leads to edit their own workflows and screens without affecting other projects or global schemes. This targeted delegation ensures that the central IT team is no longer burdened by low-value requests, allowing them to focus on high-level IT Service Management Solutions that drive long-term business value. Establishing an internal certification program further reinforces this model, ensuring that every delegated admin possesses a verified understanding of how their actions impact the broader ecosystem.

The Project Lead Empowerment Model

Shifting routine tasks such as version management, component updates, and basic workflow transitions to the project level is a primary driver of operational efficiency. Organizations that successfully implement a delegated model often report a reduction in the central administrative ticket queue by up to 40%, as teams no longer wait for external approval for minor adjustments. By setting clear guardrails and providing standardized templates, you ensure that team leads can innovate within their own workspace while the integrity of the global reduce jira administration overhead strategy remains intact. This approach fosters a culture of ownership and accountability, which is essential for maintaining a high-performance digital infrastructure.

Maintaining Oversight in a Decentralized Model

Effective delegation must be paired with robust oversight to prevent the gradual drift of configuration standards. Utilizing audit logs to monitor changes made by delegated administrators provides the transparency needed to maintain a secure and compliant environment. Regular ‘Health Check’ synchronizations between central IT and project leads serve as a proactive measure to identify potential issues before they escalate into systemic problems. This combination of trust and verification ensures that the platform remains agile, secure, and perfectly aligned with the organization’s evolving needs. If you’re ready to transform your administrative model from a bottleneck into a catalyst for growth, speak with our governance experts today to design your delegated roadmap.

Strategic Managed Services: Offloading Operational Complexity

Maintaining a high-performance Atlassian environment is a continuous endeavor that often exceeds the bandwidth of internal IT departments focused on broader digital transformation goals. While the governance and automation strategies discussed previously are vital, the sheer scale of global enterprise requirements can still overwhelm even the most disciplined teams. Deciding to reduce jira administration overhead through a strategic partnership allows your organization to offload the technical “heavy lifting” to experts who live and breathe the Atlassian ecosystem. This transition ensures that your platform remains optimized, secure, and ready to scale without exhausting your internal human capital.

The ROI of professional intervention becomes clear when you consider the cost of downtime and the complexity of modern compliance. Our Managed Outsourcing Services provide a structured approach to platform health, offering predictable operational costs and the peace of mind that comes from professional oversight. Enterprises often leverage managed outsourcing to maintain the continuous support and system health required for global operations, ensuring that technical debt never accumulates to the point of system failure.

The Value Proposition of Atlassian Consulting

Specialized consultants bring a level of technical rigor that’s difficult to replicate in-house, particularly when navigating high-stakes initiatives like Data Center to Cloud migrations. With the March 2029 end-of-life for Data Center products approaching, the need for precise, compliant transition planning is paramount. Professional consultants ensure that your environment meets rigorous standards, including GDPR and HIPAA requirements where necessary. For a comprehensive look at how a strategic partner can catalyze your growth, explore our Atlassian Consulting Services Dublin guide.

Tailored Support for Global Enterprises

A managed service model offers the flexibility to scale administrative support up or down based on your current project demand, ensuring you’re never paying for more than you need. This adaptability is crucial for global enterprises that require consistent system health across multiple time zones and business units. By establishing guaranteed service levels, you move away from the “best effort” internal support model toward a professionalized environment where performance is measured and optimized.

  • Access to senior-level architects for complex integrations and API management.
  • Continuous system health monitoring and proactive configuration cleanup.
  • Strategic roadmap planning aligned with Atlassian’s seasonal release cadence.
  • Rapid resolution of complex technical debt and configuration sprawl.

Ultimately, the goal is to transform your Atlassian suite from a source of administrative friction into a seamless engine for productivity. To reduce jira administration overhead permanently, you need a combination of internal governance and external expertise. Ready to secure your platform’s future? Optimize your Atlassian ecosystem with Test Triangle and reclaim your team’s time for the work that truly matters.

Securing Your Platform’s Future Through Strategic Governance

Achieving operational excellence within the Atlassian ecosystem is a continuous journey that requires a fundamental shift from manual fixes to systemic frameworks. By integrating the governance policies, automation triggers, and delegation models discussed in this guide, you move beyond the ‘reactive admin’ cycle. This transition doesn’t just save time; it builds a foundation for long-term scalability and system health.

To reduce jira administration overhead permanently, you need a partner who understands the complexities of enterprise-scale digital infrastructure. As an Atlassian Platinum Solution Partner with proven success in global enterprise migrations and specialized expertise in highly regulated industries like Pharma, we offer the technical rigor needed to optimize your environment. It’s time to transform your platform from a maintenance burden into a catalyst for progress.

Streamline your Atlassian environment with our expert consulting services and empower your team to focus on the strategic innovation that drives your business forward. We’re ready to help you navigate this evolution with confidence.

Frequently Asked Questions

How can I identify which Jira custom fields are safe to delete?

Identifying safe candidates for deletion requires a systematic audit of field population and usage frequency across your entire instance. You should utilize the Custom Field Optimizer available in Jira Data Center or leverage Marketplace applications to generate a report on fields with zero percent population or those that haven’t been updated in the last 12 months. Once identified, these fields should be moved to a “sandbox” environment for testing before permanent removal to ensure no critical reporting dependencies are broken.

What is the difference between a Jira Administrator and a Project Administrator?

Jira Administrators possess global system authority, allowing them to manage system settings, global schemes, and user directories that affect the entire instance. In contrast, Project Administrators are restricted to managing localized settings within a specific project, such as versions, components, and certain workflow transitions. This distinction is vital for maintaining a secure environment while allowing teams enough autonomy to manage their daily operational needs without central intervention.

Can I automate the removal of users to save on license costs?

You can effectively reduce jira administration overhead by integrating Jira with an Identity Provider (IdP) like Okta or Azure AD through SCIM provisioning. This setup allows for the automated deactivation of users based on their status in your central HR directory or Active Directory. Additionally, administrators can deploy scripts to identify and deactivate users who haven’t logged in for 90 days, ensuring your license count remains optimized without manual reconciliation.

How do I prevent my Jira instance from becoming slow due to overhead?

Preventing performance degradation requires a proactive commitment to configuration hygiene and systemic standardization. You should strictly limit the number of custom fields, as exceeding 700 fields per space can significantly slow down issue indexing and administrative navigation. Consolidating redundant permission schemes and performing regular system re-indexing are also critical actions that protect system responsiveness and ensure a stable experience for all global users.

Is it possible to delegate administration without giving away full system access?

Delegating authority is possible through the ‘Extended Project Administration’ permission, which empowers project leads to modify their own screens and workflows. This feature allows for localized flexibility while keeping global system configurations and security settings locked under the control of central administrators. It’s an effective way to reduce jira administration overhead by shifting minor tactical requests away from the central IT ticket queue.

How often should I perform a Jira health check and cleanup?

Enterprises should conduct a comprehensive system health check at least once per quarter to identify configuration drift and performance bottlenecks. Monthly reviews are recommended for license optimization and user cleanup to maintain financial discipline. Aligning these deep-dive audits with Atlassian’s seasonal release cadence ensures your environment remains compatible with the latest features and security patches, providing long-term operational stability.

What are the benefits of using shared schemes in Jira?

Shared schemes provide a unified architectural foundation that ensures consistency across multiple projects, significantly simplifying the administrative burden. When you update a shared permission or notification scheme, the changes propagate instantly across all associated projects, eliminating the need for manual, project-by-project updates. This approach reduces the risk of human error and ensures that your global governance policies are enforced universally across the entire enterprise.

When should an enterprise consider a Managed Service Provider for Jira?

An enterprise should consider a Managed Service Provider when internal IT teams are consistently overwhelmed by low-value support tickets or face complex technical challenges like a Cloud migration. Partnering with a specialized firm is particularly beneficial for organizations in highly regulated industries that require guaranteed SLAs and expert-level compliance oversight. This model allows your internal talent to focus on strategic innovation while external experts handle the complex operational maintenance.

Paul Guy

Article by

Paul Guy

Paul serves as the Marketing Director at Test Triangle, where he leads a global team in driving growth through strategic B2B marketing and brand communications. With a strong emphasis on measurable outcomes and sustainable performance, he plays a pivotal role in aligning marketing functions to enhance customer engagement and accelerate business impact. Under his leadership, marketing initiatives have consistently delivered significant returns on investment, elevated brand visibility, and strengthened the company's presence across key markets.